GTFormer: What If Long Context Didn’t Need Attention At All...
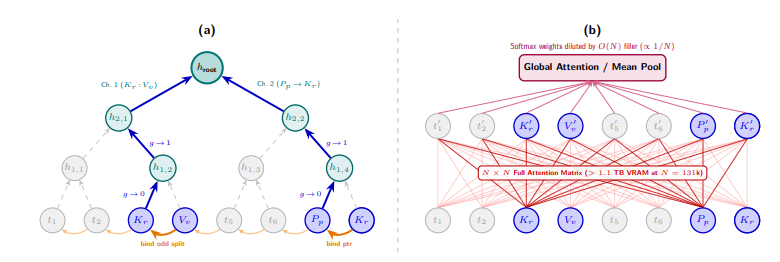
A new preprint trains a model on just 512 tokens and runs it on 4 million without any fine tuning. It does this by dropping self attention completely.
D
2 min read
Share a technical deep-dive, system design breakdown, or engineering tutorial with the CSI MIT-WPU community.
A new preprint trains a model on just 512 tokens and runs it on 4 million without any fine tuning. It does this by dropping self attention completely.
Chrome, Firefox, Apple and Microsoft all cut off certificates from Bengaluru-based eMudhra within days. The cause was a set of keys that should have been random and weren’t.