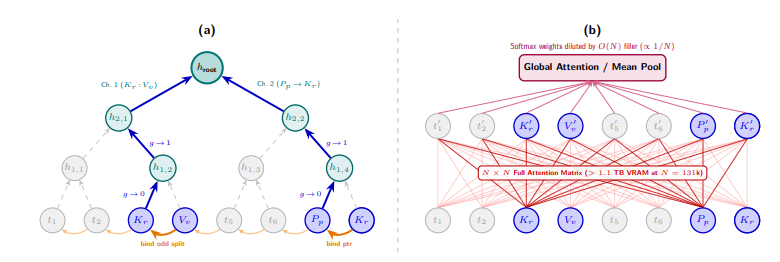
The Engineering Bottleneck Self attention compares every token with every other token, so cost grows quadratically with length. On top of that, models usually fall apart on sequences longer than what they saw in training, even when compute is not the limit. Most fixes only patch this. Sparse attention, RoPE tweaks and Mamba style state models all help, but each gives something up, usually recall or reliability at extreme lengths.
GTFormer, posted to arXiv by Elisabeth Fink, takes a different route. It treats the sequence as a graph. Tokens get merged bottom up in a binary tree, neighbours are linked sideways, and a few random expander edges act as shortcuts across long distances. Every node has a bounded number of connections, so cost stays linear. Position is encoded by where a token sits in the tree, so there is no positional embedding to break at longer lengths.
Production Takeaway
The reported results are strong. Perplexity matches comparable Transformers on Wikitext 103 and C4, and long context tasks stay accurate up to 4M tokens on a single GPU. But it is a single author preprint, trained only at 512 tokens, tested on encoder style tasks, with no Mamba comparison and no text generation results yet. I would treat it as a design idea worth watching, not a replacement for attention.
Full paper at: https://arxiv.org/abs/2610.37524