@Darshan Nayak
1
Posts
0
Followers
2
Likes
Comments
Tech Weekly
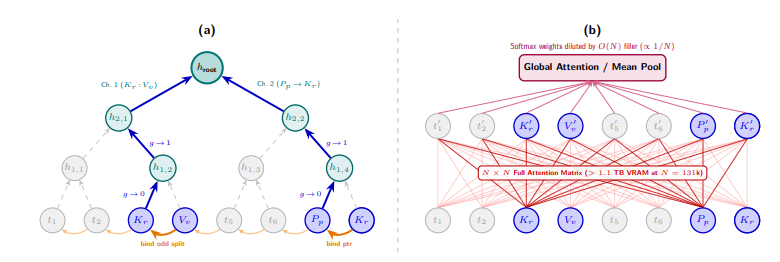
A new preprint trains a model on just 512 tokens and runs it on 4 million without any fine tuning. It does this by dropping self attention completely.